01
Ray & Wave Optics
Designing and inverting the optical front end: how light propagates through lenses and diffractive elements.
- Computer-generated holography Image
- Lens design Text
Computational imaging benchmark · 2026
Can AI Solve Imaging Problems? Benchmarking Multimodal AI for Image Formation and Reconstruction
1CIRP Lab, University of Hawaiʻi at Mānoa 2Texas A&M University 3Glass Imaging 4University of North Carolina at Charlotte
* Equal contribution
Overview
Vision–language models and image-editing models have strong semantic visual skills. Whether they have learned the image formation behind scientific and computational imaging, and can invert it, is largely unexplored.
ImagingBench gives a model a description of the image-formation process, the input measurements and the task context, and asks it to produce the target image directly: no external code execution and no task-specific optimization. That isolates how much of the physics the model has actually internalized.
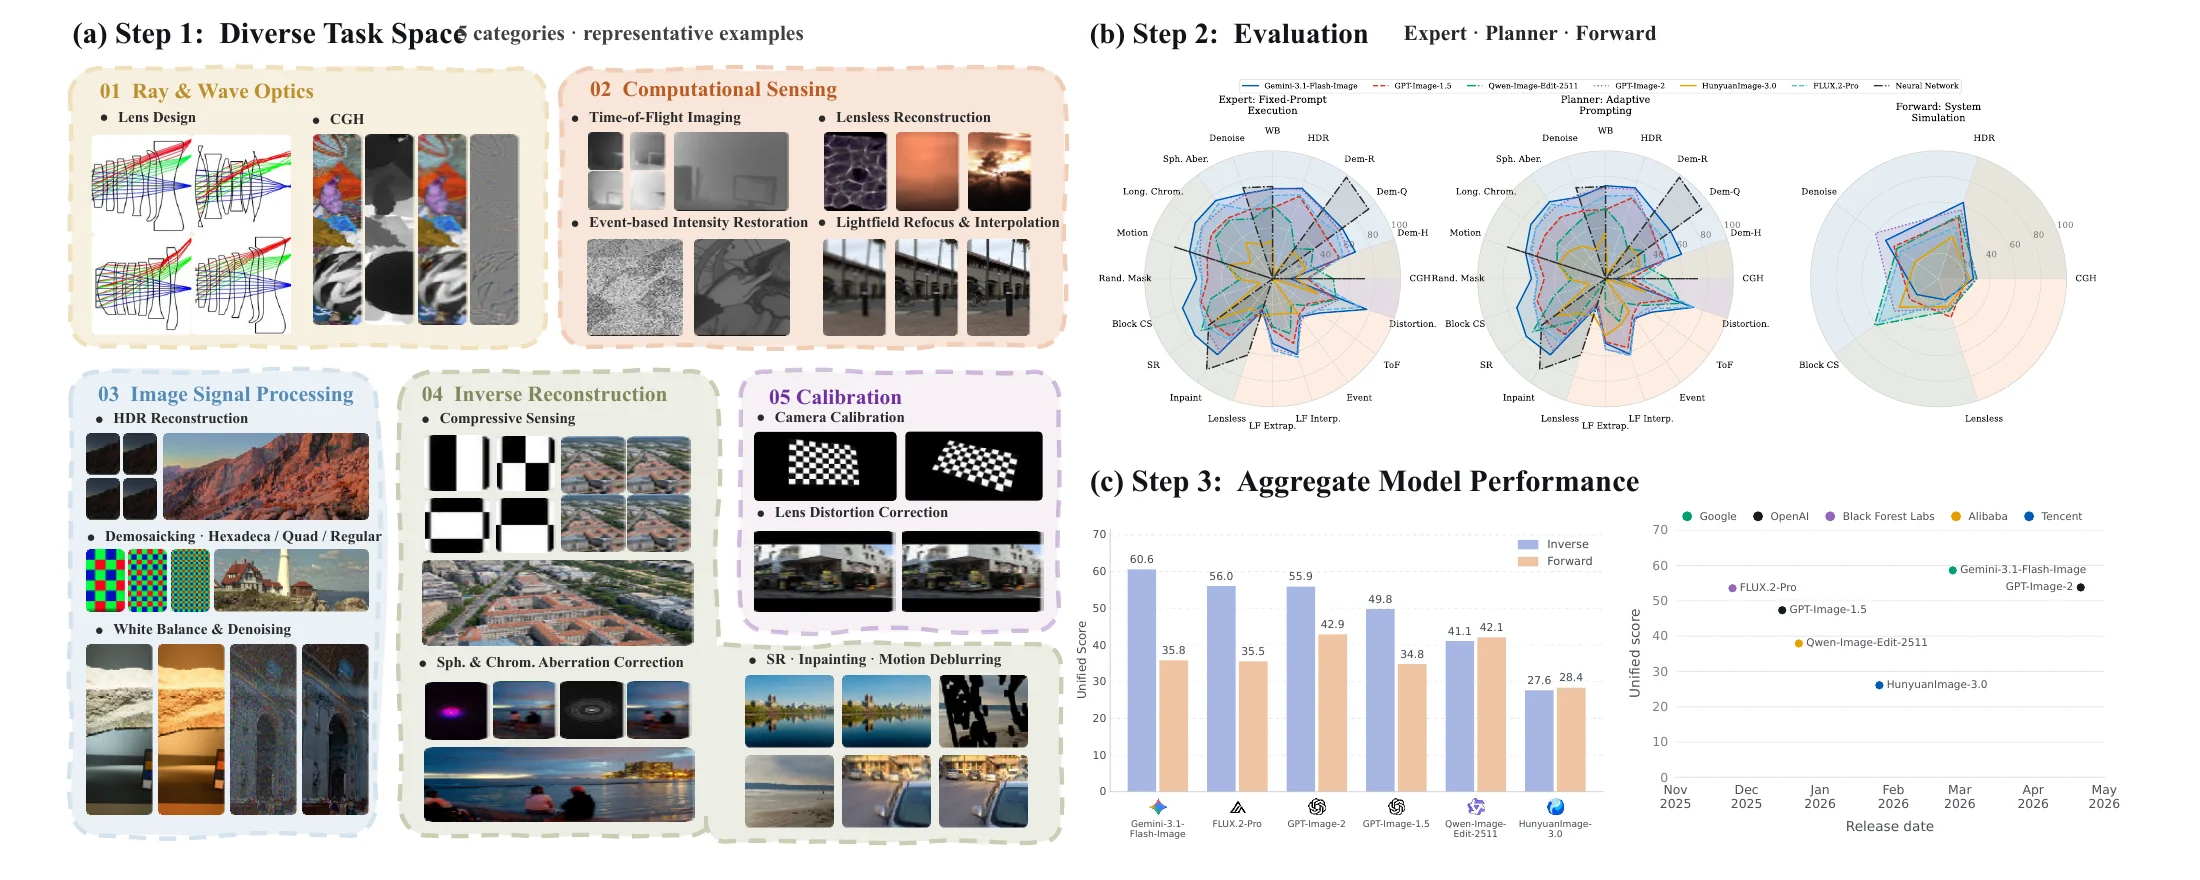
Tasks
Tasks follow the imaging pipeline, from the optics that form an image to the sensor, the processing chain and the reconstruction that recovers a scene. Twenty tasks produce images and feed the leaderboard; lens design and camera calibration produce text and are scored separately.
Designing and inverting the optical front end: how light propagates through lenses and diffractive elements.
The camera's processing chain: from raw sensor values to a clean, correctly coloured photograph.
Undoing a known degradation: blur, aberration, sub-sampling and missing pixels.
Non-conventional cameras whose measurements look nothing like the scene until they are inverted.
Recovering a camera's geometry: intrinsics from checkerboards and correction of lens distortion.
Per-category and per-task scores for every model and protocol, with specialized neural-network baselines alongside.
Protocols
Inverse reconstruction with a fixed, domain-expert prompt for each task. The editor sees the measurement and the expert instruction, and returns the reconstruction.
measurement + expert prompt → editor → image
A frontier VLM first writes an image-specific restoration plan; the same editor then executes it. Comparing with Expert isolates the effect of planning.
measurement → VLM planner → adaptive prompt → editor → image
The reverse direction: given a clean image, simulate the measurement a physical system would record. Tests forward–inverse consistency on five tasks.
clean image → VLM planner → forward prompt → editor → measurement
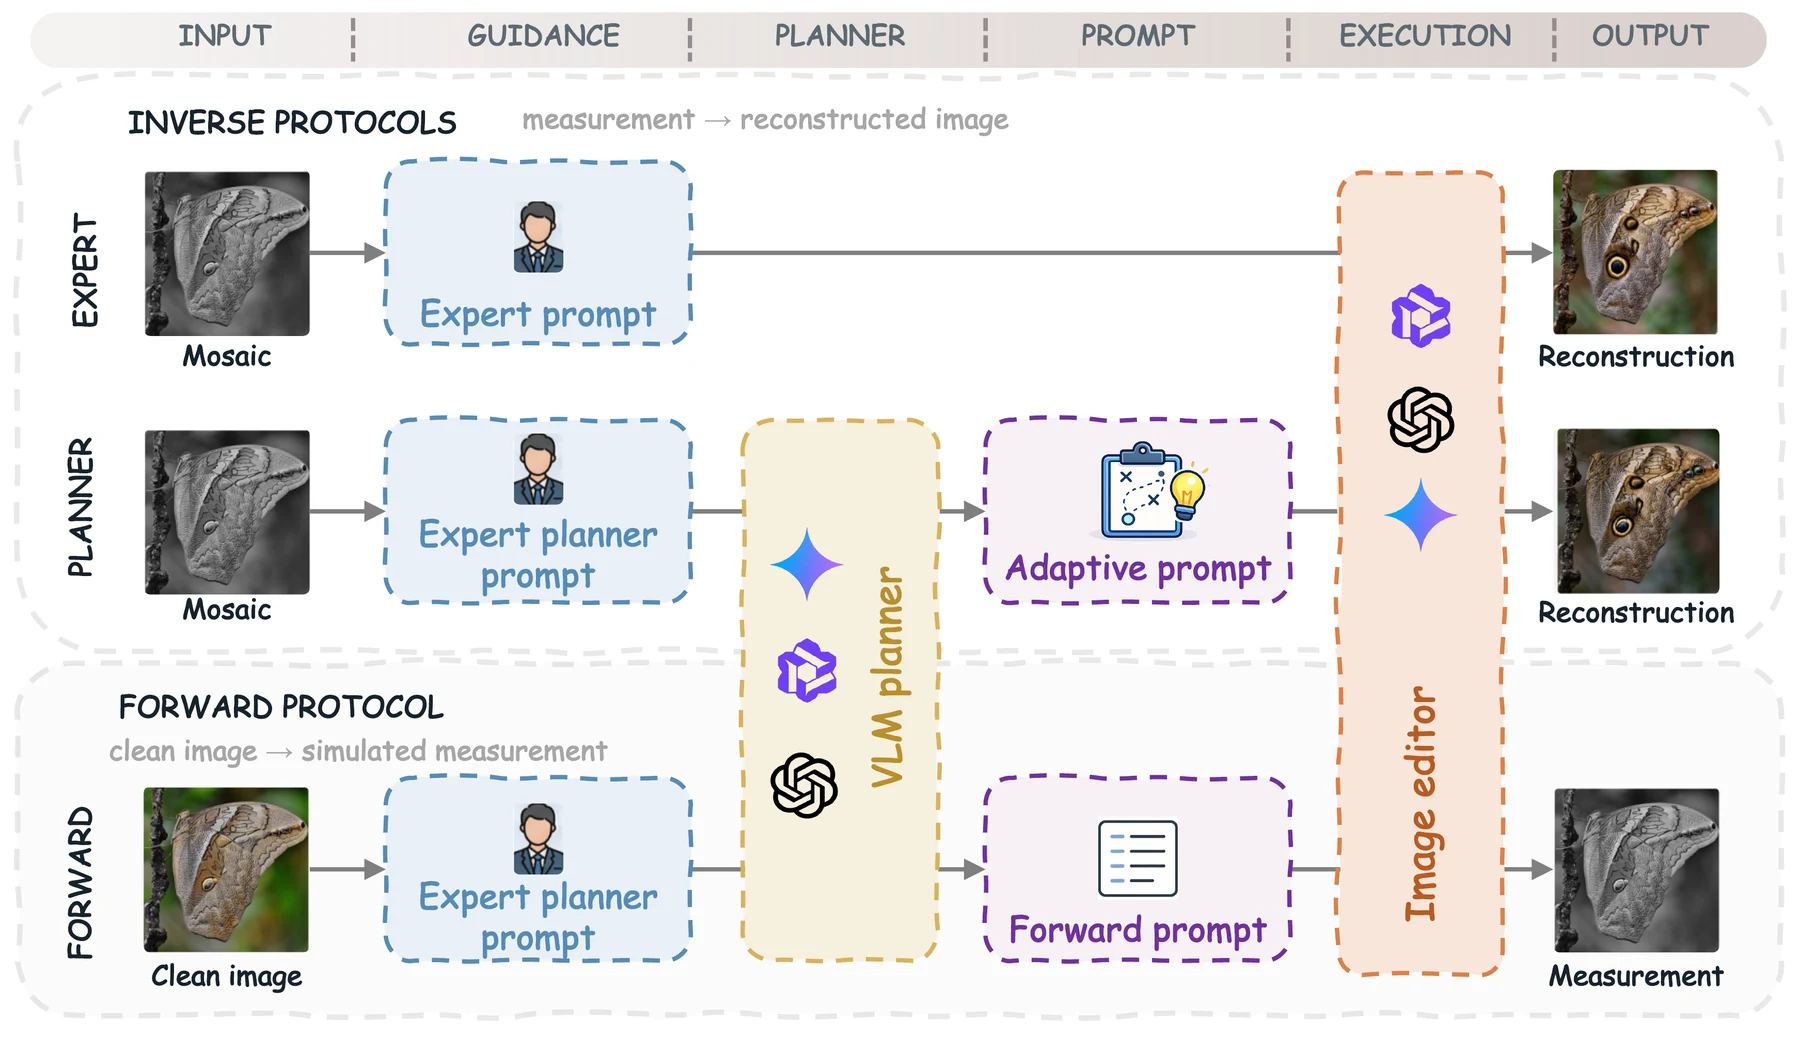
Results
| # | Model | Access | Expert | Planner | Forward |
|---|---|---|---|---|---|
| Loading… | |||||
The unified score normalizes each signal to [0, 1] (e.g. PSNR / 40, 1 − LPIPS, VLM-judge score / 100) and takes a weighted mean per instance. The weights were fitted to 2,665 blind pairwise judgments by 28 human raters. CGH, ToF depth and Forward outputs, which are not natural photographs, use the unweighted mean of four full-reference metrics.
Gallery
Real prompts and real outputs for every image task, from all six models. Pick a category, a task and a protocol to compare the input, the reference and each model's result. Click any image to enlarge.
Loading…
Images are compressed to WebP for the web.
Findings
Where a specialized baseline exists (9 of 20 image tasks) it usually leads, most clearly in PSNR: by at least 15 dB on demosaicking, 11 dB on lensless imaging, 8 dB on holography and 6.5 dB on denoising. Super-resolution is the exception, where Gemini beats an ESRGAN reference.
Tasks that require inverting a sensing operator fail worst. Under Expert, lensless imaging, event reconstruction and holography average only 7.6, 9.0 and 9.4 dB PSNR; on those inputs models return textures or a different scene altogether.
Planner guidance changes Overall by −3.2 to +2.3 points, and five of six models lose slightly. The editor matters more than the plan; on the cost frontier Qwen reaches 42.7 at no API cost and Gemini 61.4 at $0.066 per image.
Pixel metrics can hide large failures. On demosaicking, GPT-Image-2 returns grayscale images for 59% of Planner inputs: its judge score halves (68.3 → 32.2) while its PSNR does not move. The planner's step-by-step recipes often never say the output should be in colour.
Simulating a measurement from a clean image is not easy either. GPT-Image-2 (42.9) and Qwen (42.1) lead, ahead of Gemini (35.8); all six models score between 28.4 and 42.9.
Citation
Citation details will appear here once the preprint is public.